Understanding Backward Torch Ones Like X in PyTorch
When you dive into deep learning with PyTorch, the backward pass is a core concept that lets your model learn from error signals. This article walks you through the mechanics of PyTorch’s backward propagation, how to modify operations for custom gradients, and practical tips for efficient training. Whether you’re following a self‑study video or attending a lightning talk, you’ll find clear, code‑focused explanations that help you master this vital feature.
What Is the Backward Pass?
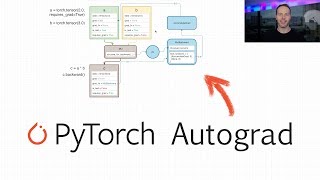
The backward pass, often called gradient descent, propagates error gradients from the loss function back through each layer of a neural network. In PyTorch, you trigger this by calling loss.backward(). PyTorch automatically builds a computational graph during the forward pass, storing each operation’s inputs and outputs. This graph is then traversed in reverse to compute gradients for all tensors that require gradients.
Key Components of the Computational Graph
- Tensor: Multi‑dimensional array that holds data and its gradient.
- grad_fn: Function that produced the tensor; used during backpropagation.
- requires_grad: Flag that tells PyTorch to track operations on a tensor.
Why Modify Operations in the Backward Pass?
Sometimes the default gradient calculation isn’t what you need. For example, you might want to clip gradients, apply custom regularization, or implement a new activation function with a non‑standard derivative. PyTorch lets you define custom gradients by subclassing torch.autograd.Function and implementing forward and backward static methods.
Sample Custom Function
Below is a simplified illustration of a custom ReLU that clamps gradients below a threshold. Remember, in real code you would use torch.autograd.Function syntax, but the logic remains the same.
- Define the forward pass: def forward(ctx, input): ctx.save_for_backward(input) return input.clamp(min=0)
- Define the backward pass: def backward(ctx, grad_output): input, = ctx.saved_tensors grad_input = grad_output.clone() grad_input[input < 0] = 0 grad_input[grad_output < threshold] = 0 return grad_input
This example shows how you can intercept gradient values and manipulate them before they’re passed to earlier layers.